


Pass Databricks Databricks-Machine-Learning-Associate Exam Info and Free Practice Test
New 2026 Latest Questions Databricks-Machine-Learning-Associate Dumps - Use Updated Databricks Exam
Databricks Databricks-Machine-Learning-Associate Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 20
A data scientist wants to tune a set of hyperparameters for a machine learning model. They have wrapped a Spark ML model in the objective function objective_function and they have defined the search space search_space.
As a result, they have the following code block: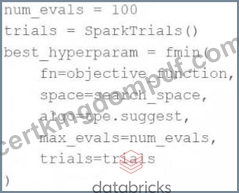
Which of the following changes do they need to make to the above code block in order to accomplish the task?
- A. Reduce num_evals to be less than 10
- B. Change SparkTrials() to Trials()
- C. Remove the algo=tpe.suggest argument
- D. Remove the trials=trials argument
- E. Change fmin() to fmax()
Answer: B
Explanation:
The SparkTrials() is used to distribute trials of hyperparameter tuning across a Spark cluster. If the environment does not support Spark or if the user prefers not to use distributed computing for this purpose, switching to Trials() would be appropriate. Trials() is the standard class for managing search trials in Hyperopt but does not distribute the computation. If the user is encountering issues with SparkTrials() possibly due to an unsupported configuration or an error in the cluster setup, using Trials() can be a suitable change for running the optimization locally or in a non-distributed manner.
Reference
Hyperopt documentation: http://hyperopt.github.io/hyperopt/
NEW QUESTION # 21
Which of the following describes the relationship between native Spark DataFrames and pandas API on Spark DataFrames?
- A. pandas API on Spark DataFrames are single-node versions of Spark DataFrames with additional metadata
- B. pandas API on Spark DataFrames are made up of Spark DataFrames and additional metadata
- C. pandas API on Spark DataFrames are unrelated to Spark DataFrames
- D. pandas API on Spark DataFrames are more performant than Spark DataFrames
- E. pandas API on Spark DataFrames are less mutable versions of Spark DataFrames
Answer: B
Explanation:
Pandas API on Spark (previously known as Koalas) provides a pandas-like API on top of Apache Spark. It allows users to perform pandas operations on large datasets using Spark's distributed compute capabilities. Internally, it uses Spark DataFrames and adds metadata that facilitates handling operations in a pandas-like manner, ensuring compatibility and leveraging Spark's performance and scalability.
Reference
pandas API on Spark documentation: https://spark.apache.org/docs/latest/api/python/user_guide/pandas_on_spark/index.html
NEW QUESTION # 22
A data scientist is working with a feature set with the following schema: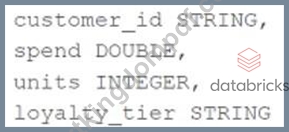
The customer_id column is the primary key in the feature set. Each of the columns in the feature set has missing values. They want to replace the missing values by imputing a common value for each feature.
Which of the following lists all of the columns in the feature set that need to be imputed using the most common value of the column?
- A. customer_id
- B. loyalty_tier
- C. customer_id, loyalty_tier
- D. spend
- E. units
Answer: B
Explanation:
For the feature set schema provided, the columns that need to be imputed using the most common value (mode) are typically the categorical columns. In this case, loyalty_tier is the only categorical column that should be imputed using the most common value. customer_id is a unique identifier and should not be imputed, while spend and units are numerical columns that should typically be imputed using the mean or median values, not the mode.
Reference:
Databricks documentation on missing value imputation: Handling Missing Data If you need any further clarification or additional questions answered, please let me know!
NEW QUESTION # 23
Which of the following machine learning algorithms typically uses bagging?
- A. IGradient boosted trees
- B. K-means
- C. Random forest
- D. Decision tree
Answer: C
Explanation:
Random Forest is a machine learning algorithm that typically uses bagging (Bootstrap Aggregating). Bagging is a technique that involves training multiple base models (such as decision trees) on different subsets of the data and then combining their predictions to improve overall model performance. Each subset is created by randomly sampling with replacement from the original dataset. The Random Forest algorithm builds multiple decision trees and merges them to get a more accurate and stable prediction.
Reference:
Databricks documentation on Random Forest: Random Forest in Spark ML
NEW QUESTION # 24
A machine learning engineer is trying to perform batch model inference. They want to get predictions using the linear regression model saved at the path model_uri for the DataFrame batch_df.
batch_df has the following schema:
customer_id STRING
The machine learning engineer runs the following code block to perform inference on batch_df using the linear regression model at model_uri: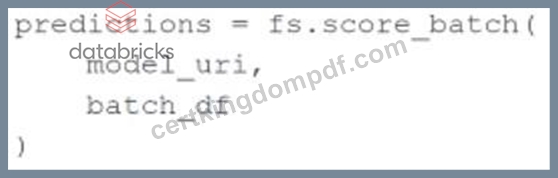
In which situation will the machine learning engineer's code block perform the desired inference?
- A. When all of the features used by the model at model_uri are in a single Feature Store table
- B. This code block will not perform the desired inference in any situation.
- C. When all of the features used by the model at model_uri are in a Spark DataFrame in the PySpark
- D. When the model at model_uri only uses customer_id as a feature
- E. When the Feature Store feature set was logged with the model at model_uri
Answer: E
Explanation:
The code block provided by the machine learning engineer will perform the desired inference when the Feature Store feature set was logged with the model at model_uri. This ensures that all necessary feature transformations and metadata are available for the model to make predictions. The Feature Store in Databricks allows for seamless integration of features and models, ensuring that the required features are correctly used during inference.
Reference:
Databricks documentation on Feature Store: Feature Store in Databricks
NEW QUESTION # 25
A machine learning engineer wants to parallelize the training of group-specific models using the Pandas Function API. They have developed the train_model function, and they want to apply it to each group of DataFrame df.
They have written the following incomplete code block: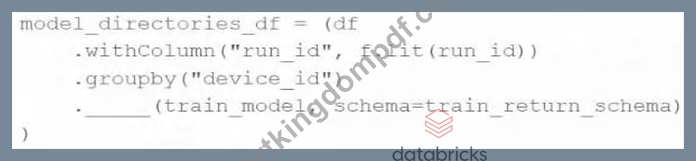
Which of the following pieces of code can be used to fill in the above blank to complete the task?
- A. groupedApplyIn
- B. applyInPandas
- C. mapInPandas
- D. train_model
- E. predict
Answer: C
Explanation:
The function mapInPandas in the PySpark DataFrame API allows for applying a function to each partition of the DataFrame. When working with grouped data, groupby followed by applyInPandas is the correct approach to apply a function to each group as a separate Pandas DataFrame. However, if the function should apply across each partition of the grouped data rather than on each individual group, mapInPandas would be utilized. Since the code snippet indicates the use of groupby, the intent seems to be to apply train_model on each group specifically, which aligns with applyInPandas. Thus, applyInPandas is a better fit to ensure that each group generated by groupby is processed through the train_model function, preserving the partitioning and grouping integrity.
Reference
PySpark Documentation on applying functions to grouped data: https://spark.apache.org/docs/latest/api/python/reference/api/pyspark.sql.GroupedData.applyInPandas.html
NEW QUESTION # 26
A machine learning engineer would like to develop a linear regression model with Spark ML to predict the price of a hotel room. They are using the Spark DataFrame train_df to train the model.
The Spark DataFrame train_df has the following schema: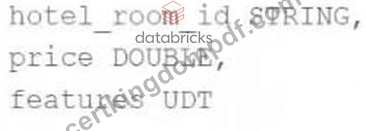
The machine learning engineer shares the following code block:
Which of the following changes does the machine learning engineer need to make to complete the task?
- A. They do not need to make any changes
- B. They need to split the features column out into one column for each feature
- C. They need to convert the features column to be a vector
- D. They need to utilize a Pipeline to fit the model
- E. They need to call the transform method on train df
Answer: C
Explanation:
In Spark ML, the linear regression model expects the feature column to be a vector type. However, if the features column in the DataFrame train_df is not already in this format (such as being a column of type UDT or a non-vectorized type), the engineer needs to convert it to a vector column using a transformer like VectorAssembler. This is a critical step in preparing the data for modeling as Spark ML models require input features to be combined into a single vector column.
Reference
Spark MLlib documentation for LinearRegression: https://spark.apache.org/docs/latest/ml-classification-regression.html#linear-regression
NEW QUESTION # 27
A data scientist learned during their training to always use 5-fold cross-validation in their model development workflow. A colleague suggests that there are cases where a train-validation split could be preferred over k-fold cross-validation when k > 2.
Which of the following describes a potential benefit of using a train-validation split over k-fold cross-validation in this scenario?
- A. A holdout set is not necessary when using a train-validation split
- B. Fewer models need to be trained when using a train-validation split
- C. Bias is avoidable when using a train-validation split
- D. Reproducibility is achievable when using a train-validation split
- E. Fewer hyperparameter values need to be tested when using a train-validation split
Answer: B
Explanation:
A train-validation split is often preferred over k-fold cross-validation (with k > 2) when computational efficiency is a concern. With a train-validation split, only two models (one on the training set and one on the validation set) are trained, whereas k-fold cross-validation requires training k models (one for each fold).
This reduction in the number of models trained can save significant computational resources and time, especially when dealing with large datasets or complex models.
Reference:
Model Evaluation with Train-Test Split
NEW QUESTION # 28
The implementation of linear regression in Spark ML first attempts to solve the linear regression problem using matrix decomposition, but this method does not scale well to large datasets with a large number of variables.
Which of the following approaches does Spark ML use to distribute the training of a linear regression model for large data?
- A. Logistic regression
- B. Least-squares method
- C. Singular value decomposition
- D. Iterative optimization
Answer: D
Explanation:
For large datasets, Spark ML uses iterative optimization methods to distribute the training of a linear regression model. Specifically, Spark MLlib employs techniques like Stochastic Gradient Descent (SGD) and Limited-memory Broyden-Fletcher-Goldfarb-Shanno (L-BFGS) optimization to iteratively update the model parameters. These methods are well-suited for distributed computing environments because they can handle large-scale data efficiently by processing mini-batches of data and updating the model incrementally.
Reference:
Databricks documentation on linear regression: Linear Regression in Spark ML
NEW QUESTION # 29
A machine learning engineer has created a Feature Table new_table using Feature Store Client fs. When creating the table, they specified a metadata description with key information about the Feature Table. They now want to retrieve that metadata programmatically.
Which of the following lines of code will return the metadata description?
- A. fs.get_table("new_table")
- B. There is no way to return the metadata description programmatically.
- C. fs.create_training_set("new_table")
- D. fs.get_table("new_table").description
- E. fs.get_table("new_table").load_df()
Answer: D
Explanation:
To retrieve the metadata description of a feature table created using the Feature Store Client (referred here as fs), the correct method involves calling get_table on the fs client with the table name as an argument, followed by accessing the description attribute of the returned object. The code snippet fs.get_table("new_table").description correctly achieves this by fetching the table object for "new_table" and then accessing its description attribute, where the metadata is stored. The other options do not correctly focus on retrieving the metadata description.
Reference:
Databricks Feature Store documentation (Accessing Feature Table Metadata).
NEW QUESTION # 30
A machine learning engineer is trying to scale a machine learning pipeline by distributing its single-node model tuning process. After broadcasting the entire training data onto each core, each core in the cluster can train one model at a time. Because the tuning process is still running slowly, the engineer wants to increase the level of parallelism from 4 cores to 8 cores to speed up the tuning process. Unfortunately, the total memory in the cluster cannot be increased.
In which of the following scenarios will increasing the level of parallelism from 4 to 8 speed up the tuning process?
- A. When the data is particularly long in shape
- B. When the data is particularly wide in shape
- C. When the entire data can fit on each core
- D. When the model is unable to be parallelized
- E. When the tuning process in randomized
Answer: C
Explanation:
Increasing the level of parallelism from 4 to 8 cores can speed up the tuning process if each core can handle the entire dataset. This ensures that each core can independently work on training a model without running into memory constraints. If the entire dataset fits into the memory of each core, adding more cores will allow more models to be trained in parallel, thus speeding up the process.
Reference:
Parallel Computing Concepts
NEW QUESTION # 31
An organization is developing a feature repository and is electing to one-hot encode all categorical feature variables. A data scientist suggests that the categorical feature variables should not be one-hot encoded within the feature repository.
Which of the following explanations justifies this suggestion?
- A. One-hot encoding is computationally intensive and should only be performed on small samples of training sets for individual machine learning problems.
- B. One-hot encoding is a potentially problematic categorical variable strategy for some machine learning algorithms.
- C. One-hot encoding is dependent on the target variable's values which differ for each apaplication.
- D. One-hot encoding is not a common strategy for representing categorical feature variables numerically.
Answer: B
Explanation:
The suggestion not to one-hot encode categorical feature variables within the feature repository is justified because one-hot encoding can be problematic for some machine learning algorithms. Specifically, one-hot encoding increases the dimensionality of the data, which can be computationally expensive and may lead to issues such as multicollinearity and overfitting. Additionally, some algorithms, such as tree-based methods, can handle categorical variables directly without requiring one-hot encoding.
Reference:
Databricks documentation on feature engineering: Feature Engineering
NEW QUESTION # 32
An organization is developing a feature repository and is electing to one-hot encode all categorical feature variables. A data scientist suggests that the categorical feature variables should not be one-hot encoded within the feature repository.
Which of the following explanations justifies this suggestion?
- A. One-hot encoding is computationally intensive and should only be performed on small samples of training sets for individual machine learning problems.
- B. One-hot encoding is not supported by most machine learning libraries.
- C. One-hot encoding is dependent on the target variable's values which differ for each application.
- D. One-hot encoding is a potentially problematic categorical variable strategy for some machine learning algorithms.
- E. One-hot encoding is not a common strategy for representing categorical feature variables numerically.
Answer: D
Explanation:
One-hot encoding transforms categorical variables into a format that can be provided to machine learning algorithms to better predict the output. However, when done prematurely or universally within a feature repository, it can be problematic:
Dimensionality Increase: One-hot encoding significantly increases the feature space, especially with high cardinality features, which can lead to high memory consumption and slower computation.
Model Specificity: Some models handle categorical variables natively (like decision trees and boosting algorithms), and premature one-hot encoding can lead to inefficiency and loss of information (e.g., ordinal relationships).
Sparse Matrix Issue: It often results in a sparse matrix where most values are zero, which can be inefficient in both storage and computation for some algorithms.
Generalization vs. Specificity: Encoding should ideally be tailored to specific models and use cases rather than applied generally in a feature repository.
Reference
"Feature Engineering and Selection: A Practical Approach for Predictive Models" by Max Kuhn and Kjell Johnson (CRC Press, 2019).
NEW QUESTION # 33
A data scientist has replaced missing values in their feature set with each respective feature variable's median value. A colleague suggests that the data scientist is throwing away valuable information by doing this.
Which of the following approaches can they take to include as much information as possible in the feature set?
- A. Refrain from imputing the missing values in favor of letting the machine learning algorithm determine how to handle them
- B. Create a binary feature variable for each feature that contained missing values indicating whether each row's value has been imputed
- C. Impute the missing values using each respective feature variable's mean value instead of the median value
- D. Create a constant feature variable for each feature that contained missing values indicating the percentage of rows from the feature that was originally missing
- E. Remove all feature variables that originally contained missing values from the feature set
Answer: B
Explanation:
By creating a binary feature variable for each feature with missing values to indicate whether a value has been imputed, the data scientist can preserve information about the original state of the data. This approach maintains the integrity of the dataset by marking which values are original and which are synthetic (imputed). Here are the steps to implement this approach:
Identify Missing Values: Determine which features contain missing values.
Impute Missing Values: Continue with median imputation or choose another method (mean, mode, regression, etc.) to fill missing values.
Create Indicator Variables: For each feature that had missing values, add a new binary feature. This feature should be '1' if the original value was missing and imputed, and '0' otherwise.
Data Integration: Integrate these new binary features into the existing dataset. This maintains a record of where data imputation occurred, allowing models to potentially weight these observations differently.
Model Adjustment: Adjust machine learning models to account for these new features, which might involve considering interactions between these binary indicators and other features.
Reference
"Feature Engineering for Machine Learning" by Alice Zheng and Amanda Casari (O'Reilly Media, 2018), especially the sections on handling missing data.
Scikit-learn documentation on imputing missing values: https://scikit-learn.org/stable/modules/impute.html
NEW QUESTION # 34
A machine learning engineer wants to parallelize the inference of group-specific models using the Pandas Function API. They have developed the apply_model function that will look up and load the correct model for each group, and they want to apply it to each group of DataFrame df.
They have written the following incomplete code block: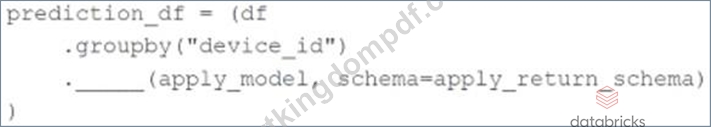
Which piece of code can be used to fill in the above blank to complete the task?
- A. groupedApplyInPandas
- B. predict
- C. applyInPandas
- D. mapInPandas
Answer: C
Explanation:
To parallelize the inference of group-specific models using the Pandas Function API in PySpark, you can use the applyInPandas function. This function allows you to apply a Python function on each group of a DataFrame and return a DataFrame, leveraging the power of pandas UDFs (user-defined functions) for better performance.
prediction_df = ( df.groupby("device_id") .applyInPandas(apply_model, schema=apply_return_schema) ) In this code:
groupby("device_id"): Groups the DataFrame by the "device_id" column.
applyInPandas(apply_model, schema=apply_return_schema): Applies the apply_model function to each group and specifies the schema of the return DataFrame.
Reference:
PySpark Pandas UDFs Documentation
NEW QUESTION # 35
Which of the following tools can be used to distribute large-scale feature engineering without the use of a UDF or pandas Function API for machine learning pipelines?
- A. Keras
- B. PyTorch
- C. Spark ML
- D. Scikit-learn
Answer: C
Explanation:
Spark MLlib is a machine learning library within Apache Spark that provides scalable and distributed machine learning algorithms. It is designed to work with Spark DataFrames and leverages Spark's distributed computing capabilities to perform large-scale feature engineering and model training without the need for user-defined functions (UDFs) or the pandas Function API. Spark MLlib provides built-in transformations and algorithms that can be applied directly to large datasets.
Reference:
Databricks documentation on Spark MLlib: Spark MLlib
NEW QUESTION # 36
A data scientist is wanting to explore summary statistics for Spark DataFrame spark_df. The data scientist wants to see the count, mean, standard deviation, minimum, maximum, and interquartile range (IQR) for each numerical feature.
Which of the following lines of code can the data scientist run to accomplish the task?
- A. spark_df.describe().head()
- B. spark_df.toPandas()
- C. spark_df.printSchema()
- D. spark_df.summary ()
- E. spark_df.stats()
Answer: D
Explanation:
The summary() function in PySpark's DataFrame API provides descriptive statistics which include count, mean, standard deviation, min, max, and quantiles for numeric columns. Here are the steps on how it can be used:
Import PySpark: Ensure PySpark is installed and correctly configured in the Databricks environment.
Load Data: Load the data into a Spark DataFrame.
Apply Summary: Use spark_df.summary() to generate summary statistics.
View Results: The output from the summary() function includes the statistics specified in the query (count, mean, standard deviation, min, max, and potentially quartiles which approximate the interquartile range).
Reference
PySpark Documentation: https://spark.apache.org/docs/latest/api/python/reference/api/pyspark.sql.DataFrame.summary.html
NEW QUESTION # 37
The implementation of linear regression in Spark ML first attempts to solve the linear regression problem using matrix decomposition, but this method does not scale well to large datasets with a large number of variables.
Which of the following approaches does Spark ML use to distribute the training of a linear regression model for large data?
- A. Logistic regression
- B. Least-squares method
- C. Singular value decomposition
- D. Spark ML cannot distribute linear regression training
- E. Iterative optimization
Answer: E
Explanation:
For large datasets with many variables, Spark ML distributes the training of a linear regression model using iterative optimization methods. Specifically, Spark ML employs algorithms such as Gradient Descent or L-BFGS (Limited-memory Broyden-Fletcher-Goldfarb-Shanno) to iteratively minimize the loss function. These iterative methods are suitable for distributed computing environments and can handle large-scale data efficiently by partitioning the data across nodes in a cluster and performing parallel updates.
Reference:
Spark MLlib Documentation (Linear Regression with Iterative Optimization).
NEW QUESTION # 38
A data scientist is using Spark ML to engineer features for an exploratory machine learning project.
They decide they want to standardize their features using the following code block: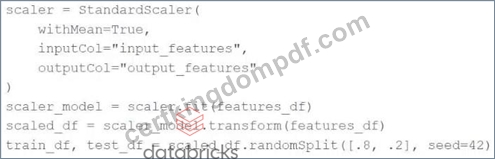
Upon code review, a colleague expressed concern with the features being standardized prior to splitting the data into a training set and a test set.
Which of the following changes can the data scientist make to address the concern?
- A. Utilize the MinMaxScaler object to standardize the test data according to global minimum and maximum values
- B. Utilize the Pipeline API to standardize the test data according to the training data's summary statistics
- C. Utilize the Pipeline API to standardize the training data according to the test data's summary statistics
- D. Utilize the MinMaxScaler object to standardize the training data according to global minimum and maximum values
- E. Utilize a cross-validation process rather than a train-test split process to remove the need for standardizing data
Answer: B
Explanation:
To address the concern about standardizing features prior to splitting the data, the correct approach is to use the Pipeline API to ensure that only the training data's summary statistics are used to standardize the test data. This is achieved by fitting the StandardScaler (or any scaler) on the training data and then transforming both the training and test data using the fitted scaler. This approach prevents information leakage from the test data into the model training process and ensures that the model is evaluated fairly.
Reference:
Best Practices in Preprocessing in Spark ML (Handling Data Splits and Feature Standardization).
NEW QUESTION # 39
......
Latest Databricks-Machine-Learning-Associate Exam Dumps Databricks Exam: https://www.certkingdompdf.com/Databricks-Machine-Learning-Associate-latest-certkingdom-dumps.html